Jowin Jestine

I build the data platform a clinical lab runs on.

I am a data engineer at Olaris, a metabolomics diagnostics company in Boston. In practice I own the platform: the Azure infrastructure, the ingestion pipelines, the deployment path, and the internal applications that the lab uses every day. Most of it is invisible until something breaks, which is the honest description of infrastructure work.

The work is interesting because of the constraint. Everything runs inside a CLIA-regulated, HIPAA-bound boundary, so a design cannot only be correct on the happy path. It has to stay traceable when a sample is pooled, when a vendor drops a message, when a result is corrected six weeks later, and when the person who built it is on holiday.

Jowin Jestine

Looking for Platform and data-architecture work where correctness is not negotiable: regulated or high-consequence data, in diagnostics, finance, or anywhere a wrong answer costs something real. Based in Boston. If that is what you are hiring for, say hello.

Point at a peak, or press the arrow keys, to see what it is.

Figure 1. A 1D proton NMR spectrum of urine, which is the raw material almost everything below is built on. Chemical shift runs high to low, left to right, by convention, and the gap in the middle is where the water resonance is suppressed. Each peak is a metabolite. The job of the platform is to make sure the sample that produced this trace can still be tied back to a patient, an order and a report months later.
Role
Data Engineer III, Olaris
Based
Boston, Massachusetts
Before
Boehringer Ingelheim, Cigna, UConn
Published
iScience, Cell Press, 2025

Selected work

These are systems I built and still own at Olaris, written up as decisions rather than achievements, because the decisions are the part that transfers. Where a figure is quoted, it is one I already publish on my CV.

Eight things that have gone wrong in a production lab. Pick one and I will show you what it took to stop it happening again.

Sample inventory that does not trust the webhook

Keeping a PostgreSQL inventory in step with the lab's electronic notebook, given a vendor webhook that loses messages in production.

The vendor’s webhooks lose events in production. Nothing errors, so the database quietly stops matching the freezer.

Lab notebookReceiverQueueProcessorPostgreSQLReconcilerObject storelossyenqueuedequeueon changescheduled pollbackfill missingarchive raw payload

Figure 2. Two paths write the same records. The dashed webhook is fast and unreliable; the scheduled reconciliation is slower and complete. Step through it to see why losing an event only delays a row.
How it stops trusting the webhook

The problem

The lab's inventory lives in an electronic lab notebook. Our database needs to reflect it closely enough that a scientist can trust a query instead of walking to a freezer. The vendor offers webhooks, and the obvious design is to receive each event and write it down.

That design fails quietly. In production, a measurable share of webhook deliveries never arrive. Nothing errors. The database simply drifts from reality, and the first symptom is somebody being told a sample exists when it does not. A system that is wrong but confident is worse than one that is visibly down.

What I decided, and why

Treat webhook delivery as a hint, not as the source of truth

The receiver's only job is to accept the payload, put it on a queue, and return immediately. It does no parsing and no business logic, so a malformed or surprising payload cannot cost us the event. Correctness moved out of the request path entirely, which also means the vendor's retry behaviour stops being our problem.

Reconcile on a schedule instead of hoping for completeness

Because delivery cannot be relied on, a scheduled job walks the notebook's API over a look-back window and compares it against what we hold. Anything missing is pulled in. This is the part that turns completeness from a hope into a property: the steady state is correct even if every webhook in a window is lost.

A second scheduled job does a different thing, and keeping them separate matters. Reconciliation asks “is anything missing?”. Change detection asks “has anything I already hold been edited?”. Those questions have different look-back windows and different costs, and a single job doing both ends up doing neither well.

Detect change by hashing fields, not by trusting timestamps

Reconciliation naively implemented would rewrite everything on every pass, which destroys any useful audit history and makes real changes impossible to see. Each record's meaningful fields are hashed, so a pass can tell the difference between “seen again” and “actually changed”, and only genuine changes are written.

Give every event a receipt, and make the receipt the source of safety

Each event gets a row recording where it is: queued, processing, or finished. That row is what makes reprocessing safe, because the same event arriving twice finds its own receipt rather than creating a second sample.

The subtle case is a crash halfway through. The queue makes the message visible again after a timeout, and the receipt is still sitting in processing. Matching that state, rather than only matching untouched work, is what lets the retry resume instead of quietly discarding the message. Treating a half-finished receipt as if it were finished is the bug that would be hardest to notice.

ReceivedQueuedProcessingDonethe receipt is what a retry matches on

Figure 3. Every event gets a receipt row, and the row is what makes reprocessing safe. The third step is the one worth reading: a half-finished receipt has to be recognised as resumable.
Archive the raw payload before interpreting it

Every payload lands in object storage exactly as received, before any parsing. When a mapping turns out to be wrong months later, the original is still there, and there is an endpoint that feeds archived payloads back through the same processing path to rebuild the history. Parsing logic is the thing most likely to be wrong; the raw event is the thing least likely to be.

What this guarantees

  • Inventory converges on the notebook even during a total webhook outage.
  • A lost message delays a row. It does not silently lose one.
  • Audit history shows real changes, not reconciliation noise.
  • A parsing mistake is recoverable, because the raw event was never discarded.

What I would tell someone starting this

The instinct is to make the receiver clever: validate, deduplicate, retry. That is effort spent in the one place that cannot be made reliable, because you do not control the sender. Put the cleverness in reconciliation, keep the receiver boring, and the whole system gets easier to reason about.
Identifiers that survive the exceptions

A traceability model where formal identifiers, not names typed by hand, carry the link from patient to sample to spectrum to report.

When an identifier is missing, people put the meaning in the name field. That is the one field nobody can enforce.

PatientOrderSampleAliquotSpectrumResearchsamplePooledsampleProcessedspectrumparent ofderived from
Figure 4. Every edge is a recorded relationship rather than a naming convention. A pooled sample has two parents, a research sample has no patient, and a processed spectrum points back at the acquisition it came from. None of those cases needs a workaround.
How the identifier model works

The problem

Clinical and research workflows had grown up with separate identifier schemes. Some entities had no identifier at all: a processed spectrum, for instance, could not be named in a way that distinguished it from the raw acquisition it came from.

Where identifiers were missing, names filled the gap. Names are typed by people, under time pressure, in several systems, with no enforcement. So meaning migrated into the one field guaranteed to be inconsistent. This is a slow failure: nothing crashes, workarounds become standard practice, and traceability quietly becomes partial instead of guaranteed.

What I decided, and why

Identifiers are the system of record; names are a convenience

Names stay, because people need to read something human. But nothing downstream is allowed to depend on them. Every relationship that matters is expressed as a key and a row, which means traceability stops degrading as volume grows and as more people touch the data.

A parent-and-child graph, not a linear chain

The tempting model is a chain: patient, order, sample, aliquot. It breaks on the first pooled sample, and again on the first research sample with no patient, and again on a rerun. A parent-and-child relationship at the inventory level absorbs pools, splits, reruns and collaborator material without asking the lab to change how they work. The model bends so that the people do not have to.

Design the whole architecture, then deliver it in phases

It would have been faster to ship an identifier registry alone. It would also have guaranteed drift: samples handled physically before an identifier exists, aliquots with no durable parent, corrections needing human interpretation. So the full entity model was designed up front and delivery was phased against it. Phasing the delivery is fine. Phasing the design is how you get a system that has to be replaced.

Give spectra and processed spectra real identifiers

The gap that started this project was the most valuable thing to close. Once a processed spectrum has its own identifier and a recorded parent, the chain from a patient's sample through acquisition and processing to a reported result can be walked in either direction, by a person or a query.

What this guarantees

  • Spectra and processed spectra are addressable, which they were not before.
  • Samples stay linked to patients across both product and research workflows.
  • Pooled, split and rerun material is representable without a workaround.
  • The path from sample to report can be traced in both directions.

What I would tell someone starting this

A rigid identifier scheme looks fine for about a year. Design for the exceptions you already know about, because they are not exceptions, they are the workload. And watch for meaning leaking into free-text fields; that is the earliest signal that the model is too tight.

Catching instrument drift while the instrument is still running

Monitoring NMR acquisition against reference rule sets, so an overnight batch is not discovered to be worthless in the morning.

Measured200+ acquisition parameters, each checked against its own reference range.

An overnight run can start degrading at two in the morning. Finding out at nine costs the whole night of instrument time.

AcquisitionParse runCompareWithin range: record onlyOutside range: record and alertagainst a referencerange per parameter

Figure 5. Each parameter is judged against its own reference range, so normal variation in one reading cannot raise the same alarm as meaningful drift in another. Both branches record; only one interrupts anybody.
How the thresholds are set

The problem

NMR acquisition quality depends on parameters that drift: temperature, shimming, field stability. A long overnight run can degrade partway through, and if nobody finds out until the batch completes, the cost is instrument time that cannot be recovered and clinical reporting that slips.

What I decided, and why

Compare against reference rule sets, not a single threshold

Field drift tolerance and temperature tolerance have nothing to do with each other. One global threshold does both jobs badly: it fires constantly on parameters that vary normally, and stays silent on parameters where a small movement is meaningful. Each parameter gets its own reference range, which is more configuration and considerably less noise.

Spend the effort on alert fatigue, not on detection

Detection is the easy half. An alert the team learns to ignore is worse than no alert, because it also teaches them to distrust the next one. So there are cooldowns to survive transient spikes, and notifications are grouped rather than fired per reading. I spent as long on restraint as on the checks.

Log to a database, not to files

The first version wrote quality metrics to flat files, which answers “what is happening now” and nothing else. Questions worth asking are comparative: was this parameter stable across the batch, is this instrument worse than it was last month. Those are queries, so the metrics belong in PostgreSQL, indexed by session and parameter.

Alert where the team already is

The notification goes to Microsoft Teams, because that is where the lab already works. A dashboard nobody opens is not monitoring; it is a monitoring-shaped object.

What this guarantees

  • Acquisition is checked against reference ranges on every run.
  • Drift reaches a human while the instrument is still running.
  • Quality history is queryable by session and by parameter, so trends are answerable.
  • Alert volume stays low enough that alerts still get read.

What I would tell someone starting this

Build the thresholds with the people who run the instrument, not from the specification sheet. They already know which parameters wander harmlessly and which ones mean stop. That conversation is worth more than any amount of statistical tuning.

Clinical order intake, end to end

Taking an order from a lab partner through verification, cancellation and approval into a reportable result, without anyone reconciling a spreadsheet.

MeasuredSub-second order intake. Under 0.5s response across production workloads, query latency down 75%.

Orders get cancelled. If that is someone editing a row, the audit trail is a story rather than a record.

ReceivedVerifiedAcceptedReportedCancelledAmendedan amendment returns to verification

Figure 6. Withdrawal and amendment are states with their own transitions. That is what makes the audit trail a record of what happened rather than a description of it afterwards.
How cancellation is modelled

The problem

An order arriving from an external lab partner has to become a sample, a set of measurements, and eventually a clinical report. Every step has a regulatory expectation attached, and every manual handoff is somewhere a mistake can enter without a trace.

What I decided, and why

Put a gateway in front of everything

External traffic terminates at API Management, which owns authentication, routing and policy. The functions behind it do not each re-implement a security posture, and the boundary an auditor cares about is one component rather than a diagram full of arrows.

Model cancellation as a first-class path

Orders get cancelled and amended. If that is handled by someone editing a row, the audit trail is a story rather than a record. Verification and cancellation are explicit flows with their own states, so the unhappy paths are as well-defined as the happy one, and neither needs an operator to intervene.

Secrets in Key Vault, never in configuration

Unremarkable, and worth stating because the alternative is so common. Nothing in source control or app settings holds a credential, and rotation does not require a deployment.

Approvals through the tool people already use

Report approval runs through Power Automate into Teams, as an actionable card. The approval is recorded as a state change in the database rather than living in somebody's inbox, which is the difference between a workflow and a habit.

What this guarantees

  • Order state is explicit at every point, including when an order is withdrawn.
  • The security boundary is one reviewable component, not a property of many.
  • Approvals leave a record in the database, not only in a chat history.
  • Credential rotation is an operational task, not a code change.

Making every change to a regulated app reviewable

Continuous delivery and a staging environment for clinical applications, plus immutable, serialised records of data-science output.

Reproducibility by convention does not survive a busy quarter.

Why there is only one path to production

The problem

Analytical code that influences a clinical result carries the same expectations as any other regulated artefact: you should be able to say what ran, when, on what input, and who reviewed it. Reproducibility by convention does not survive a busy quarter.

What I decided, and why

One deployment path for every application, no exceptions

Standardised pipelines mean a change reaches production the same way every time, through review and a recorded build. The value is not the automation, it is the absence of a second, undocumented route. A single exception makes the guarantee worthless.

A staging environment that actually resembles production

Refactoring a clinical application with no safe place to test it means the test is the release. Staging is unglamorous infrastructure that mostly pays off on the days you were going to make a mistake.

Write outputs once, immutably, and serialise them

Model and analysis outputs are stored so that they cannot be overwritten in place, with enough structure to be verified later. A result you can regenerate is useful; a result you can prove was the one used is what regulation is actually asking for.

The database schema is code as well

Application code being reviewed is only half of it, because a schema change can break a clinical report just as thoroughly. The logging schema is written declaratively, reviewed like any other change, and applied as ordered, checksummed migrations across more than one instance. Checksums are the part that matters: they turn “we think these databases match” into something a machine can verify.

What this guarantees

  • Every change to a clinical application is reviewed and recorded before release.
  • Schema changes are versioned and checksummed, so two instances can be proven to agree.
  • There is no informal path to production for anyone, including me.
  • A past result can be produced as evidence, not reconstructed from memory.

Processing spectra without a person driving TopSpin

Automated phasing, baseline correction and calibration for NMR acquisitions, run in parallel and audited per run.

Processing a spectrum by hand takes a trained person several minutes and no two people do it identically. Multiply that by a run of samples.

SpectrometerRaw FID storeBatch poolTaskTaskTaskProcessedsyncsubmitone spectrum per task, run in parallelauto-phase, baseline, calibrate against a reference standard
Figure 7. Raw acquisitions are synced off the spectrometer, then one processing task runs per spectrum across a pool of nodes. Each run writes its own audit record alongside the processed output, so a result can be traced to the code and the operator that produced it.
How the processing was automated

The problem

A raw acquisition is not a usable spectrum. It needs phase correction, baseline correction and calibration against a known reference before anything downstream can read it. Done by hand in the instrument software, that is several minutes of a trained person’s attention per sample, and two analysts will not produce byte-identical output from the same input.

For a research question that is tolerable. For a clinical workflow it is a reproducibility problem, because the processing itself becomes an undocumented step between the instrument and the result.

What I decided, and why

Bridge the instrument software rather than reimplement it

The instrument vendor’s software is the authority on how a spectrum is processed, and it scripts in Jython. So the automation is a thin Jython layer that drives the vendor tooling and hands off to Python 3 for the analysis, rather than a from-scratch reimplementation of well-understood spectroscopy. Writing my own phasing algorithm would have been more fun and much harder to defend.

Calibrate against a known standard, not against the tallest peak

Chemical shift referencing needs a fixed point. Calibrating to a reference compound added to the sample gives one that does not move with biology, and the processing detects the reference and navigator peaks rather than assuming where they will be.

One task per spectrum, on a pool that scales to the run

Processing is embarrassingly parallel: spectra do not depend on each other. So the work runs as a task per spectrum across a batch pool, and the same code runs locally or on the pool depending on a single mode switch. That keeps development honest, because the thing you debug on your laptop is the thing that runs on the cluster.

Every run leaves an audit record next to its output

Each run gets its own directory keyed by the ticket, the date and the operator, and writes both a human-readable log and a structured record beside the processed data. The point is not tidiness. It is that six months later you can say which code, which inputs and which person produced a given spectrum, without relying on anybody’s memory.

What this guarantees

  • The same acquisition produces the same processed spectrum every time.
  • Processing scales with the size of the run rather than the number of analysts.
  • Every processed spectrum has a record of the code, inputs and operator behind it.
  • The local and cluster paths run identical code, so one cannot drift from the other.

What I would tell someone starting this

Automate the boring, well-specified steps and leave the judgement calls alone. Phasing and baseline correction have right answers. Deciding whether a spectrum is fit to report does not, which is why that stayed a separate model with a human in the loop.

Search that understands what a compound is called

Semantic retrieval over the metabolite catalogue, running entirely inside our own cloud tenant.

Measured100K+ compounds across two diagnostic platforms. Retrieval time down 70%.

One compound has fifteen valid names. Exact-match search turns a correct query into a silent dead end.

Why the index runs in our own tenant

The problem

Metabolite lookup was exact-match. Scientific naming does not cooperate with that: one compound carries synonyms, abbreviations and structural aliases, so a correct query returns nothing and the analyst has to guess again. A silent dead end is the worst possible search result, because it looks like an answer.

What I decided, and why

Embeddings computed and indexed in-tenant

A hosted vector service would have been quicker to stand up and would have sent compound identifiers and query patterns outside the compliance boundary. A local model and a local index keep both inside it. The constraint chose the architecture, and the architecture turned out to be cheaper anyway.

Diversify results before showing them

Ranking by similarity alone fills the first page with near-duplicates of the same compound. Re-ranking for relevance and diversity together means the first screen offers chemically distinct options, which is what the analyst was actually asking for.

What this guarantees

  • Synonyms and spelling variants resolve to the same compound.
  • No embedding or query leaves the tenant.
  • The first page of results is chemically distinct, not the same molecule eight times.

A quality model that knows when to ask a human

Scoring NMR signal quality, calibrated so that uncertainty routes to review rather than guessing.

Measured10K+ observations. Analytical accuracy up 35%, manual review effort down 72%.

A bad spectrum passed off as a good one is a clinical problem, not an accuracy statistic.

recorded as failingrouted to a reviewerpasses automaticallythe midpoint, where the boundary is notless confidentmore confident
Figure 8. The decision boundary is a clinical choice rather than a modelling default. Setting it well above the midpoint means a band of uncertain spectra reaches a person, which trades throughput for not passing a bad spectrum as a good one.
How the operating point was chosen

The problem

Spectra carry noise, shimming artefacts and baseline distortion. Expert review catches these and is also the bottleneck. Automating the judgement is attractive and dangerous in equal measure, because a bad spectrum passed off as good is a clinical problem, not an accuracy statistic.

What I decided, and why

Treat the spectrum as a sequence

A tree-based model sees each frequency bin as independent, which throws away the fact that an artefact at one shift distorts its neighbours. A one-dimensional convolution over the spectrum keeps that locality, which is the entire signal here.

Calibrate the threshold well above the default

The decision boundary is not a modelling choice, it is a clinical one. A false pass is far more costly than a false flag, so the operating point is set to push uncertain spectra to a person. The model's job is to be confident only when it has earned it.

Generate failures from domain knowledge

Failing spectra are rare, so the classes are imbalanced. Oversampling the real failures risks leaking them into validation. Synthesising artefacts from known shimming error patterns produced a balanced training set while keeping validation honest.

What this guarantees

  • Low-confidence spectra go to a human instead of through the pipeline.
  • The same spectrum receives the same verdict on any day, from any reviewer.
  • Reported confidence is calibrated, so the number means something.

What I would tell someone starting this

Most of the work is not the model. It is deciding what happens when the model is unsure, and being willing to make the system slower in exchange for being right.

Writing and research

Urinary metabolite signatures to detect and differentiate graft injury in kidney transplant recipients

Dong, Trimigno, Jestine, Zhao, O’Day and Kuypers. iScience 28(9), Cell Press, 2025. doi.org/10.1016/j.isci.2025.113331

A non-invasive classifier for kidney transplant graft injury built on urinary metabolite signatures, validated against serum creatinine, which is the current clinical standard. I contributed to the data and analysis work behind it.

0.50.60.70.80.91.00.8780.5 is no better than chance1.0 is perfect separation
Figure 9. Validation AUC for the published classifier, on a scale where 0.5 carries no information. Accuracy was 86.4% across 145 patients. These numbers appear because they are published.
Validation AUC
0.878
Accuracy
86.4%
Sensitivity
95.7%
Validation cohort
43 patients

Trained on 102 patients, reaching 0.867 AUC and 84.3% accuracy, then validated on a separate 43. The figures above are the validation ones, which are the only ones worth quoting.

Writing up the clinical intake architecture

Olaris journal club

An external write-up of how an order becomes a clinical report, aimed at a mixed audience of engineers and clinical staff. I led with the constraint rather than hiding it: once you explain that a regulatory boundary decides which service may touch which data, the architecture stops looking arbitrary and starts looking necessary.

This is the part of my work I am worst at and most deliberately practising. Systems that run quietly get taken for granted, and the fix is not better systems, it is explaining them before somebody has to ask.

The receipt is what makes a retry safe

A vendor's webhooks lose events in production and nothing errors. Why reconciliation rather than a cleverer receiver is what makes an inventory complete, and why a half-finished receipt has to be treated as resumable.

Things I build on weekends

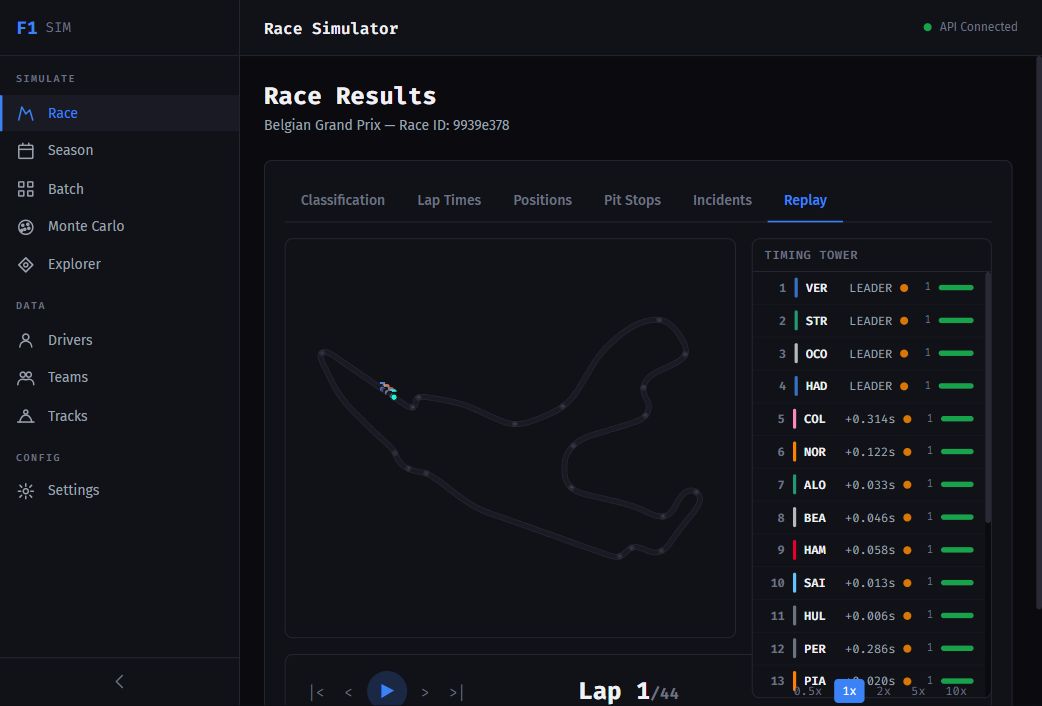
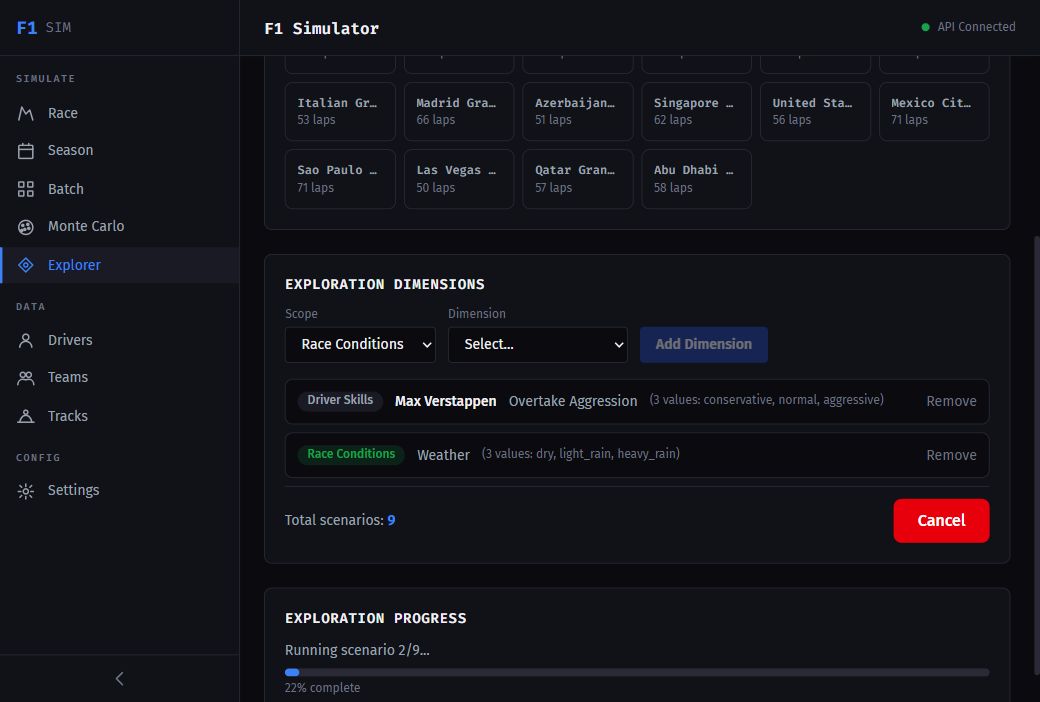
Mostly Formula 1, because it is a rich, messy, well-documented dataset with a fresh instalment every fortnight. Some of it is on GitHub; some of it is private while it is still ugly.

Public repositories

Still private, because they are still ugly

Experience

  1. 2025 to now

    Data Engineer III, Olaris

    Promoted two levels at the end of 2024, from Data Engineer I. I own the Azure estate, the ingestion pipelines, the container and deployment tooling, the database roles and schemas, and the internal applications the lab depends on: patient requisition, keyfile management, run lists and naming.

    The end-to-end analytics system runs under 0.5s response time with query latency down 75%. The HIPAA-compliant database governs 1,200+ clinical records behind role-based access, geo-fencing and audit logging, and avoids roughly $15K a year in compliance cost. Semantic search spans 100K+ metabolites across two diagnostic platforms and cut retrieval time by 70%.

  2. 2023 to 2024

    Data Engineer I, Olaris

    Consolidated the compute estate onto a single containerised host, built the first instrument monitoring service, wrote the reusable libraries for NMR ingestion and feature extraction, and organised several years of legacy raw and clinical data so that it could be found and trusted. The signal quality model trained on 10K+ observations, improving analytical accuracy by 35% and cutting manual review effort by 72%.

  3. 2022 to 2023

    Data Engineer, Biotherapeutics, Boehringer Ingelheim

    Moved thirteen research initiatives out of disconnected spreadsheets into a governed data lake with declared schemas.

  4. 2021 to 2022

    Graduate Data Science Consultant, Cigna

    Built an NLP classifier that routed IT incidents automatically, sending low-certainty tickets to human triage. Accuracy went from 30% to 87%.

  5. 2021 to 2022

    Graduate Assistant, Institutional Research, UConn

    Replaced monthly static reporting with live dashboards over 400,000 student records.

MS Business Analytics and Project Management, University of Connecticut. BE Computer Engineering, University of Mumbai.

A little more

I grew up in Mumbai taking computers apart, read Computer Engineering at the University of Mumbai, then Business Analytics at UConn, and have been in Boston since. Outside work it is Formula 1, long drives with no particular destination, and an argument with myself about whether to learn Rust properly.

I have played the piano for more than ten years, through five grades of theory and the practical exams with Trinity. It is the one discipline I have that has nothing to do with computers, and the only one where being slightly wrong is audible immediately. That turns out to be useful practice for the rest of it.

What I want next is to keep moving toward architecture: designing platforms that are traceable and compliant because of how they are built rather than because somebody remembered, and that do not depend on any single person to keep running. Including me.

Tools I reach for

Python, SQL and R. PostgreSQL, dbt, SQLMesh, DuckDB and pandas. Azure Functions, API Management, ADLS Gen2, Event Grid, Key Vault and Azure PostgreSQL. Mage AI for orchestration. Docker, Bitbucket Pipelines and Linux. FastAPI, Streamlit, NiceGUI and R Shiny for interfaces. PyTorch, XGBoost and scikit-learn when a model is genuinely the answer. On personal work, GCP: Cloud Run, BigQuery and Pub/Sub.

Languages
Python, SQL, R
Data
PostgreSQL, dbt, SQLMesh, DuckDB, pandas, PySpark
Azure
Functions, API Management, ADLS Gen2, Event Grid, Key Vault, Azure Database for PostgreSQL, Batch
Google Cloud
Cloud Run, BigQuery, Pub/Sub, Cloud Functions
Orchestration and delivery
Mage AI, Docker, Bitbucket Pipelines, GitHub Actions, Terraform, Atlas
Machine learning
PyTorch, XGBoost, scikit-learn, ONNX, MLflow, SHAP
Interfaces
FastAPI, Streamlit, NiceGUI, R Shiny, Plotly
Regulated work
CLIA, HIPAA, audit trails, de-identification, schema migrations

Get in touch

If you are building data infrastructure where correctness is not negotiable, I would like to hear about it. I usually reply within a day, unless it is a race weekend.